Oct 2026
Nwoma
Bilingual clinical document extraction and coding, English and French.
My role: Solo project
What it is
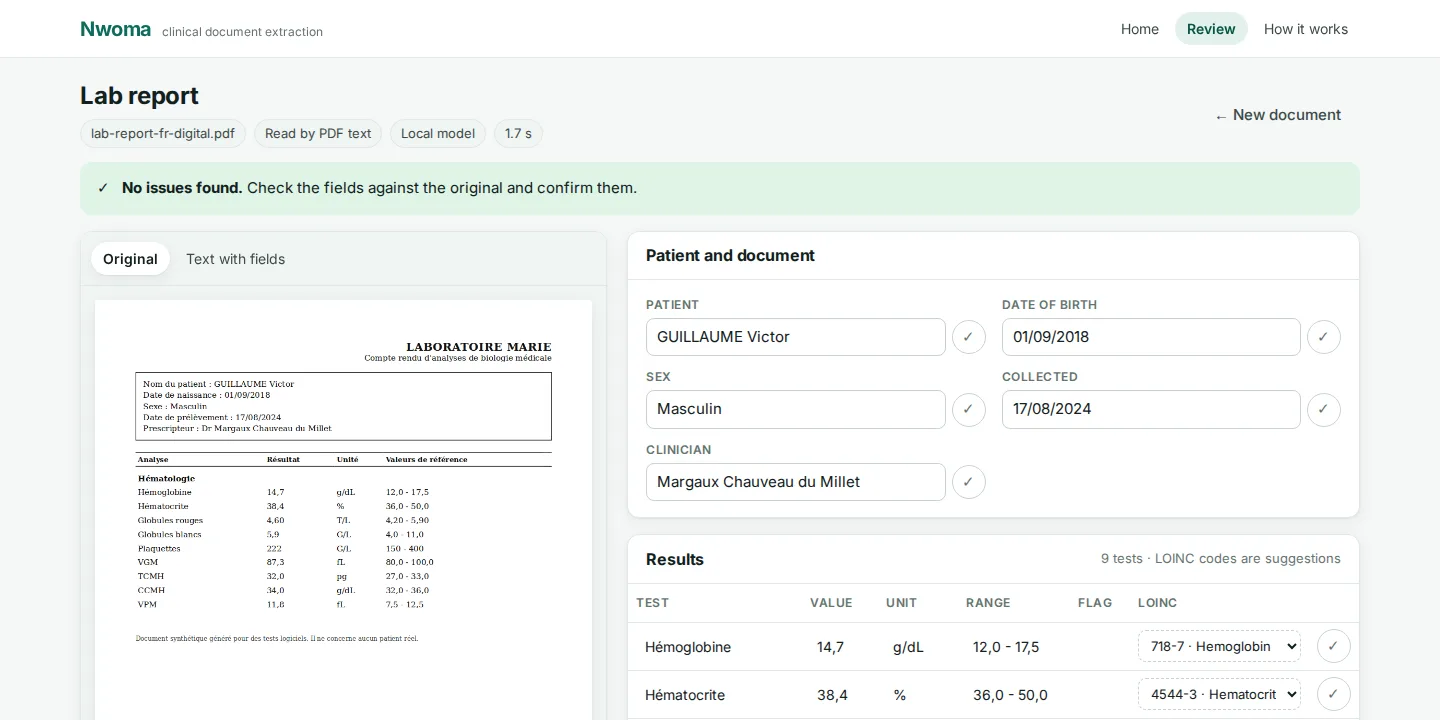
Reads lab reports and referral letters in English or French, digital or scanned, extracts 16 field types, suggests LOINC and ICD-10-CM codes, flags fields for human review and exports a FHIR R4 Bundle. It transcribes; it never diagnoses.
What I did
- Fine-tuned a multilingual XLM-R token classifier that runs on CPU in about 0.15 s per document, with Tesseract OCR for scans and a rule-based validator.
- Built a cascade that calls Gemini only when the validator rejects the local result, so 33% of documents reach the LLM.
- Built a coding agent with four tools and hybrid retrieval (keyword plus multilingual embeddings) over LOINC and ICD-10-CM.
- Wrote an MCP server that exposes extraction, coding and FHIR export to AI assistants.
- Deployed the API as an AWS Lambda container through AWS SAM and GitHub Actions OIDC, with a budget alarm that switches it off. 142 tests; nothing is stored.
Outcome
- Cascade F1 0.955 on 500 held-out synthetic documents, half French and half scanned, against 0.920 for the local model alone.
- The agent raised top-1 coding accuracy from 64% to 85.2% for LOINC and from 49% to 93.0% for ICD-10-CM.
- Published an evaluation report, a model card and architecture decision records.
Built with
- Python
- XLM-R
- FastAPI
- React
- TypeScript
- AWS Lambda
- AWS SAM
- MCP